Why Proprietary Data is Your Best Defense Against AI Scraping

AI has revolutionized the economics of information online. An informative piece can be now summarized, extracted, compared, and included in the answer to a question without the consumer of the information going back to the source. The problem for publishers and brands relying on expertise is thus to decide how much of their information can become interchangeable when machines are capable of absorbing publicly available information on a large scale.
This will not be achieved by simply publishing more pieces. It will consist in producing content that cannot be easily reproduced since its origins lie within the brand itself. Proprietary information, unique studies, first party observation, customer insights, experiments, surveys, and proprietary datasets are all ways for a brand to produce something entirely different from another piece of information available online.
What is the Issue With Easily Replicable Knowledge?
A lot of content that is created by marketers comes from knowledge that is publicly available. They compile statistics, discuss the latest trends in their industry, analyze concepts that are already understood, and give advice that has been talked about before. All such content is good and can be helpful but the problem is that it uses information that is known to everyone. It has now become easier for AI technologies to compile this information into some new content.
So, there is a problem for brands whose only advantage is informative content. When five companies are talking about the same thing, their information becomes indistinguishable. Good writing skills alone may not help if all the information in the post is already known to people. This is not an AI problem but a problem of replicable knowledge.
Proprietary Data Makes All the Difference
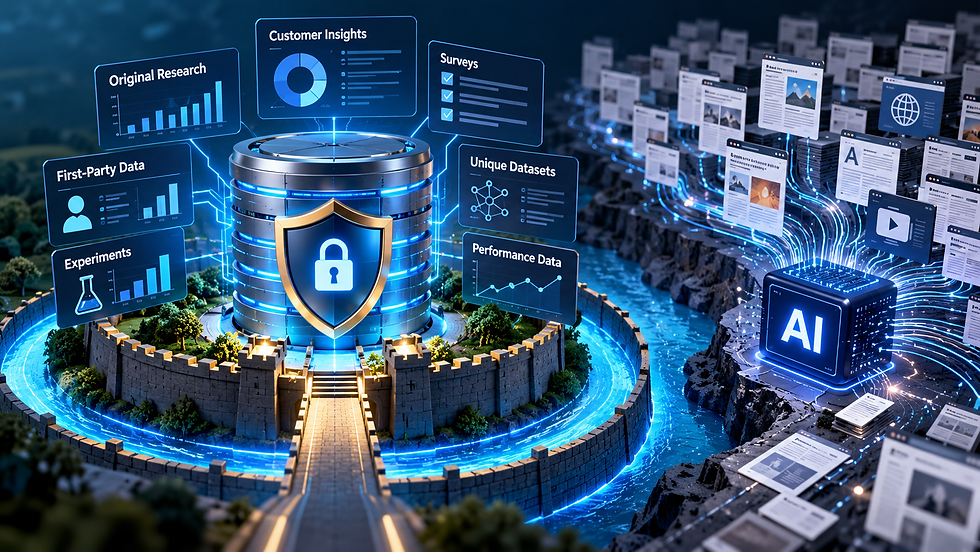
With proprietary data, a brand can possess information that is not so easily obtainable through searches on the internet. It could be anything ranging from the original research conducted on customers, performance data, product use cases, surveys, experiments, transaction data, or observations made over an extended period of time in a certain market.
This information provides context for the creation of the content, other than the information available on the internet. A brand can publish the actual findings rather than explain something that everyone else already knows. Even when AI creates summaries of such content, the information still belongs to the brand that created it.
Original Research Provides Defensible Credibility
Original research adds a special level of value to research since it provides information that one could not find by means of a simple generic search. A well-developed survey allows revealing the attitudes of a certain audience. An industry analysis may help detect the hidden tendencies. The analysis of internal performance may help identify trends that are not revealed by market reports.
Original research may provide material for the creation of various content types such as articles, presentations, social media postings, interviews, newsletters, and other forms of communication. It allows generating a whole content ecosystem based on the same evidence base. Therefore, creating one piece of original research is more valuable than developing multiple pieces of information from publicly available data.
First Party Knowledge is More Difficult to Imitate
Sometimes the most defensible type of information is generated via direct experience. If a firm has been dealing with its customers for years, it might know about some of their problems which are not available in any publicly available datasets. A software company could have insights into user behavior from thousands of customer interaction instances. A professional services firm would know how differently various firms react to an operational issue.
A software company might notice from its own customer data that users who skip a particular setup step are much more likely to contact support during their first month. That insight may not exist in any public report or article. It comes from the company's own customers and product usage.
The company can turn that finding into a short research report, an industry statistic, or a practical guide. Other companies can discuss the same topic, but they cannot easily reproduce the underlying data that produced the insight. That is what makes proprietary information valuable.
This knowledge can turn into intellectual property if recorded properly. Insights that one gets from customer conversations, anonymized behaviors, implementations and repeated questions cannot be replicated by anyone just by asking an AI program.
The key takeaway here is that proprietary knowledge need not always be confidential. A firm can make its discoveries publicly available and yet maintain an edge because of the process, the dataset, the contacts or experience involved.
Don't Try to Compete Where There is Nothing to Differentiate
AI amplifies the necessity to consider a fundamental content strategy question: What do we know that others don’t?
If the answer is nothing, creating yet another piece of content on a widely addressed topic will hardly help to differentiate. In this case, the organization might be trying to win based on presentation, distribution, or search visibility. This kind of competition might be hard to sustain since competitors could easily duplicate such approaches and AI could speed up content creation.
Proprietary data makes a differentiator much harder to imitate. Competing on how the information is presented gives way to competing on the information itself.
It doesn't mean that traditional educational content stops being relevant. It just implies that original data needs to be placed below.
Make Your Internal Data Publicly Useful
Organizations have data that would make great content material, but they are not aware of it. Sales reps hear the same objections. Customer success reps know the typical problems of implementation. Product teams notice usage patterns. Research teams know about the market. Operations teams notice performance trends.
Each of these data pieces may seem like something trivial when considered alone. In aggregate and properly analyzed, however, they can reveal important patterns.
The problem is that an organization needs to find a way to turn their data into useful information. Confidential client data should stay private and respect the limits of confidentiality, privacy, and contractual agreements. Yet, within these limitations, it is still possible to turn anonymous and aggregated data into original research that will be valuable for the market.
Create Content That AI Systems Can Cite Without Taking Your Place
It does not make sense to try to stop every possible AI system from accessing the information. It is both impractical and not necessarily the best content strategy. Instead, create content that becomes an evidence source for humans and artificial intelligence alike.
If a company releases original research results, data, methodology, or statistics, its content becomes an evidence source. Other writers can cite it. Analysts can analyze it. Industry journals can mention it. AI systems can integrate the results into the answers they provide.
What it means is that the content is doing something more than just drawing traffic. The content is becoming a source of information.
It is essential because being cited does not mean being replaced. If a company creates unique information, it will stay relevant even if the medium that brings the content to people changes.
Build Data into a Content Ecosystem
A single proprietary data set does not limit you to a single report. Research can give rise to a major study, a couple of papers, visualizations, social insights, executive summaries, presentations, and further revisions. All of these forms of content may reach different audiences but rely on the same data.
It leads to both consistency and efficiency in equal measure. Rather than continually searching for outside content to support your content, marketers now have a ready source of original content.
Most importantly, it makes the content less commoditized. You are not just making yet another interpretation of existing information online; you are adding information to the information ecosystem.
Safeguard the Source, Not Merely the Information
Data will be made strategically useful only when companies make their information assets. The way this can be done includes having proper ownership, collecting data appropriately, securing it, and determining what should be protected and what can be made public.
Not all company datasets must be marketed. They might contain personally identifiable information, commercial information, confidential customer data, or competitive data which should never be made public. Good data management is critical for any company making use of proprietary information.
It is not necessary to have maximum disclosure of the information. Rather, it is the publication of information which generates public benefit without compromising corporate interests.
A New Moat is What You Can Prove
AI may help you produce your explanations easily, but this does not mean that these explanations are evidence. A machine can create a summary based on several hundred articles written by other people, but it cannot transform general knowledge into something specific and experienced by the company itself.
This is how original data may serve as a competitive moat for any brand. It helps you have something to add instead of something to copy. This is what can prove your opinion right.
Conclusion
AI is making information in the public domain easier to replicate, summarize, and disseminate. In this scenario, generic content becomes increasingly challenging to justify as the source of differentiation. Reproducing multiple copies of information which is already available to everybody won't change anything.
Proprietary information represents an alternative option. Research work, first-hand observations, customer knowledge, experimentation, and unique data sets provide brands with information which was generated through their own experience. The result may become the basis for more distinctive, more credible, and less commodifiable content.
The goal is not to remain unseen by AI. Instead, it is to create something that the algorithm will be unable to generate on behalf of the brand: evidence generated through actual experience.
Once the brand owns the insight behind its content, it has more than just another article. It has a source. In the world where explanations start becoming abundant, the source of information may represent one of the most powerful defensibility factors a brand can achieve.


Comments